










00:00
f.01
cap twisted open.

00:02
f.02
bottle raised to mouth.
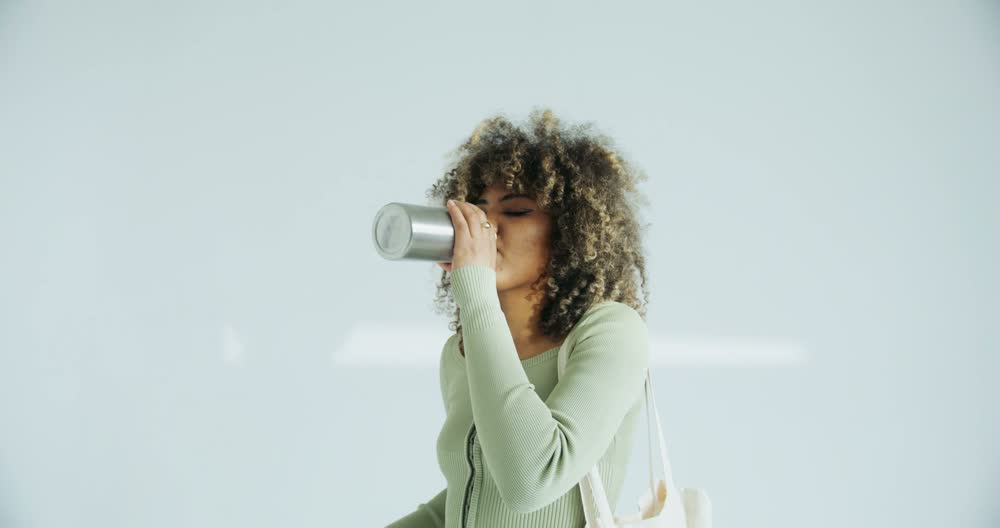
00:03
f.03
drinking.

00:06
f.04
bottle lowered from mouth.
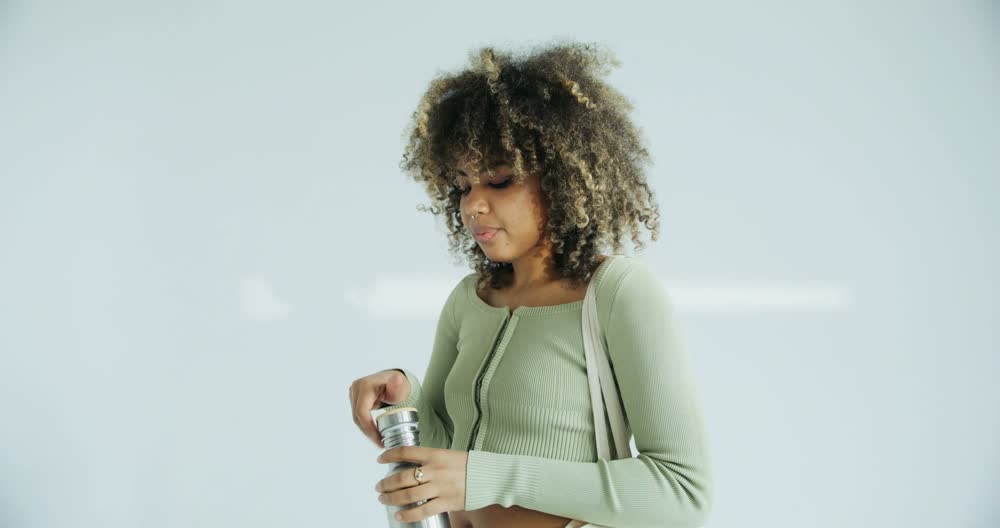
00:08
f.05
cap screwed back on.
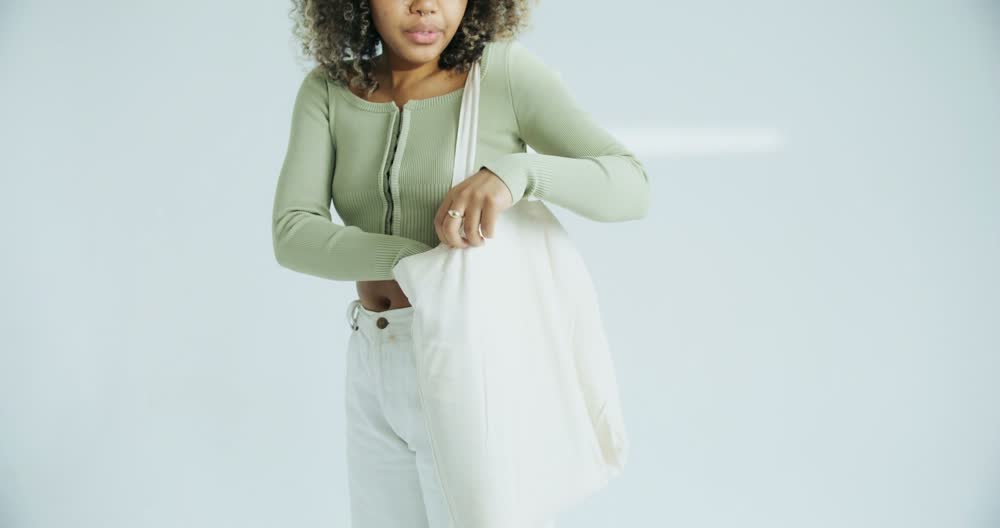
00:12
f.06
bottle placed in tote bag.
01
Find any moment by describing it.
02
Track actions and motion.
03
Detect objects, brands, logos.
04
Reason over the video, cited to the timestamp.
05
Interpret against your criteria.
06
Describe what is happening.
07
Read on-screen text.
08
Transcribe speech.
Videos processed, about 50M added every month.
Videos watched in a single batch.
Faster than real-time.
Why not just call a model API?
One engine, three ways in.
Whether you ship a product, write the code, or run a platform, the same vision AI meets you where you already work.
For product teams.
Turn your own video into a queryable asset.
For developers.
Every capability as an API and over MCP, with docs front and centre.
For platforms.
Embed vision intelligence into your product without building the pipeline.